Benchmarks
What it does, measured and dated
Ask 50 questions about one document and get every answer in about a second, on one card you own. Every number below is a measurement, with its date and its source.
- 1.08 sfor 50 questions about a 3,000-token document, Decisio 31Bone box, 2026-10-11, plain layout
- 31.7 msfor one more question about a 1,000-token text already read, Gemma 4 31B on the plain layoutdecisio 0.8.1, 585 W
- 0.035calibration error of Gemma 4 31B on JevBench's standard tier, lower is better; 0.091 on its hard tierone RTX PRO 6000, vLLM 0.30.0, 2026-10-04
Speed
Many questions about one document
On one box (one RTX PRO 6000 at 600 W, one session on 2026-10-11), Decisio 31B answered 50 questions about a 3,000-token document in 1.08 s and about a 6,000-token document in 1.73 s; Jeff-1.0-Large took 47.1 s and 114.6 s, and Quyet-1.0-Large 48.9 s and 114.8 s; neither accepts a 32,000-token document (Decisio 31B: 10.1 s). That is about 44 times (3,000 tokens) and 66 times (6,000 tokens) as long for Jeff-1.0-Large and Quyet-1.0-Large as for Decisio 31B.
On one box, the first question about a new 3,000-token document takes a median of 112 ms on H2O-Lightning-4B, 295 ms on Decisio 12B, 490 ms on Decisio 31B, and 895 ms on Jeff-1.0-Large and 895 ms on Quyet-1.0-Large.
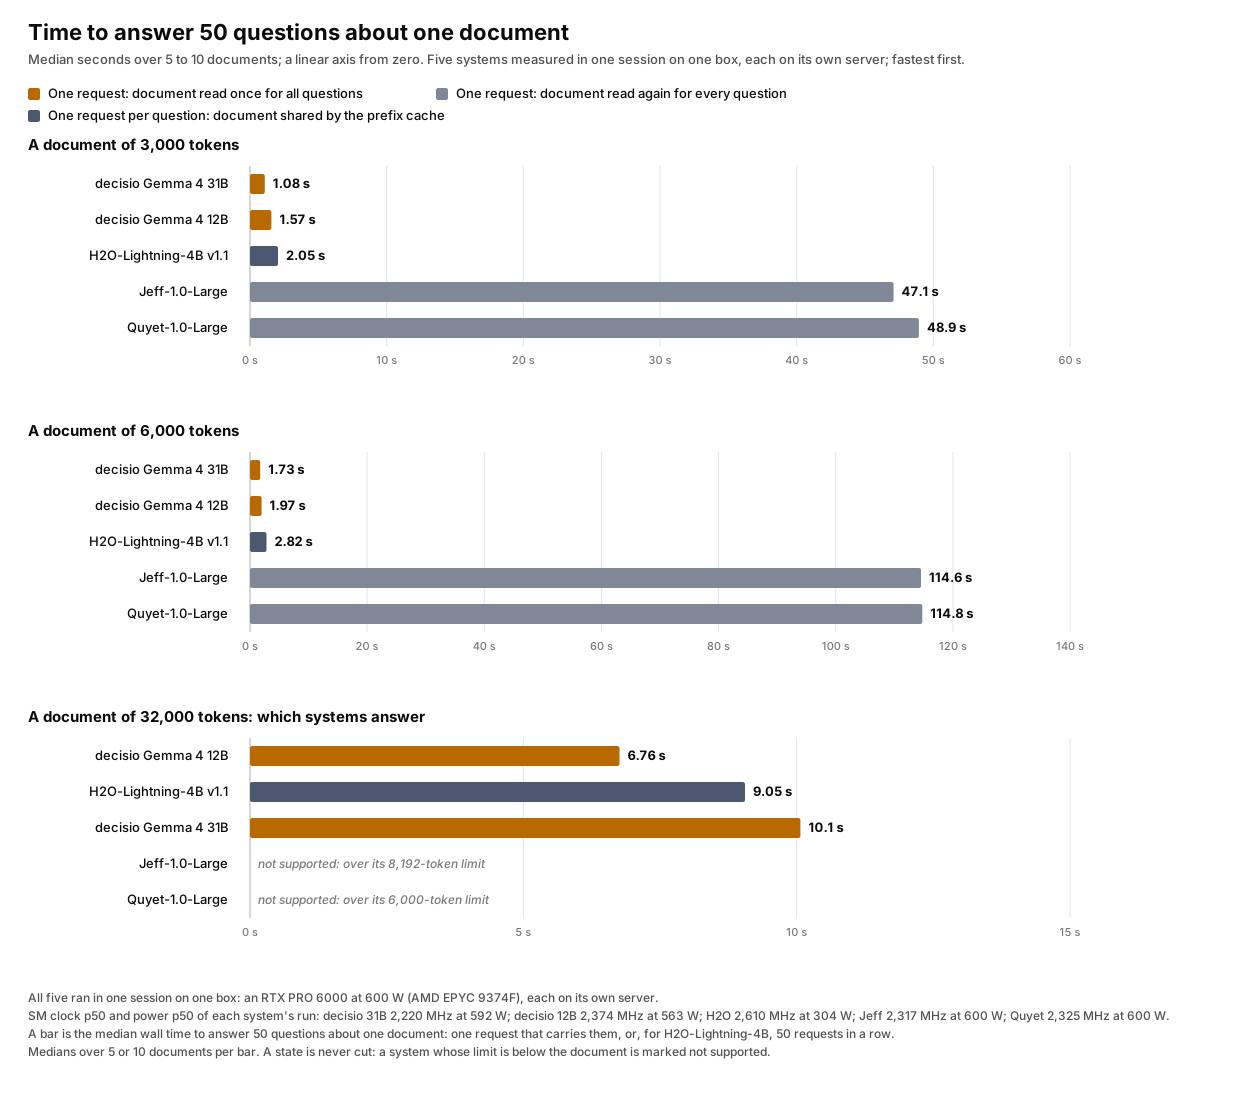
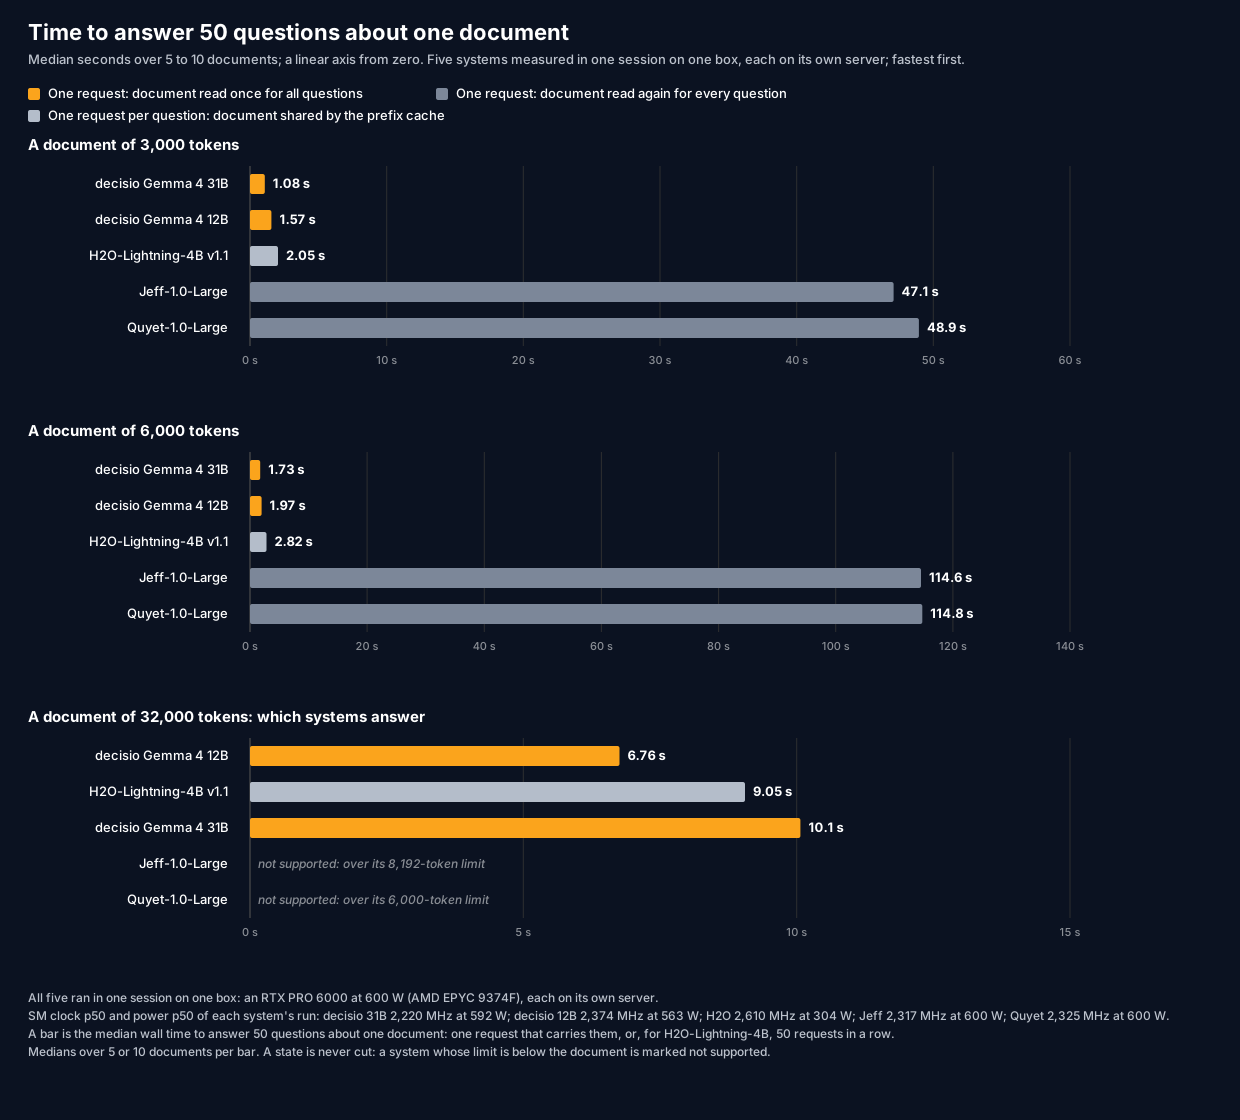
Measured by us. One box, one session: an RTX PRO 6000 at 600 W (enforced), each system on its own published server, SM clock p50 2,220 to 2,610 MHz; median of 5 or 10 documents (the count is in every cell); synthetic support tickets by the Gemma 4 tokenizer; this compares time, not accuracy.
The server was decisio v0.11.1 on vLLM 0.30.0, on the plain layout.
Each time is one request at a time; Scale says how many a card serves at once.
Each base
Choosing a base
Three models serve the same API. Each was measured by us with the public harnesses, and none of these is a board score. Choosing a model says how to pick and start each one.
- Gemma 4 31B, the default: at or above the other two on every accuracy measure in the table, and the slowest to read a new text. One NVIDIA card, measured on 96 GB and also run on an 80 GB H100, or a 64 GB Mac.
- Gemma 4 12B: the smaller Gemma, for a 32 GB Mac, or a laptop with Ollama.
- Qwen3.6-35B-A3B: the quickest to read a new text, and the only one measured with images in the text.
Accuracy and time, each base
| Measure | Qwen3.6-35B-A3BRecord: runs/2026-10-04_gemma-base/ | Gemma 4 12BRecord: runs/2026-10-04_gemma-base/ | Gemma 4 31B (default)Record: runs/2026-10-04_gemma-4-31b/ |
|---|---|---|---|
| JevBench published items, easy / standard / hard | 1.000 / 0.972 / 0.739 | 1.000 / 0.972 / 0.739 | 1.000 / 1.000 / 0.838 |
| BANKING77, macro-F1 | 0.746 | 0.729 | 0.785 |
| CLINC150+OOS, macro-F1 | 0.822 | 0.871 | 0.902 |
| GPQA Diamond, accuracy | 0.510 | 0.378 | 0.520 |
| MMLU-Pro, accuracy | 0.613 | 0.549 | 0.694 |
| Intent heads, BANKING77 / CLINC150 | 0.840 / 0.912 | 0.832 / 0.908 | 0.844 / 0.970 |
Image input, ImajevBenchRecord: runs/2026-09-27_image-input/ | 0.791 | n/m | n/m |
| New 300-token state | 49.9 ms | 53.6 ms | 80.7 ms |
| 1,000-token state, cached | 20.2 ms | 24.8 ms | 31.7 ms |
n/m is not measured.
Intent heads use labelled examples, so they are not comparable with zero-shot systems.
Latency is server time on decisio 0.8.1's served defaults, at a 585 W power limit (the default is 600 W).
Gemma 4 12B and Qwen3.6-35B-A3B on the same items, with JevBench v1.5, one RTX PRO 6000, vLLM 0.30.0, 2026-10-04
What drives the choice, measured on one RTX PRO 6000 Blackwell in one session, each base with its own defaults, paired over the same items (95% bootstrap intervals; runs/2026-10-04_gemma-base/):
| Measure | Gemma 4 12B | Qwen3.6-35B-A3B | Gemma minus Qwen |
|---|---|---|---|
| JevBench v1.5 open-set reading, I_open (equal types) | 64.4 | 49.4 | +15.0 [+7.0, +23.6] |
| JevBench v1.5, yes/no / score | 49.0 / 63.7 | 13.7 / 57.2 | |
| Yes/no answers between 0.20 and 0.80 (74 items) | 15% | 39% | |
| JevBench, published items, correct | 0.0 points [-4.3, +4.3] | ||
| Decision Index accuracy, CLINC150+OOS | +4.5 [+3.6, +5.5] | ||
| Decision Index accuracy, BANKING77 | -1.4 [-2.7, -0.1] | ||
| Decision Index accuracy, GPQA Diamond | -13.6 [-21.7, -5.6] | ||
| Decision Index accuracy, MMLU-Pro | -6.4 [-7.2, -5.5] | ||
| 1,400-item suite, accuracy | 0.735 | 0.770 | -3.5 [-5.5, -1.6] |
One question on a new 3,000-token state, server time (0.8.1's served defaults, the engine in the server's process; one RTX PRO 6000 at 585 W, AMD Ryzen Threadripper 9960X; one session, runs/2026-10-06_latency-585w/) | 258.6 ms | 85.2 ms |
Record: runs/2026-10-04_gemma-base/
Confidence
Probabilities that mean what they say
The calibration error is the average gap between the probability an answer states and how often answers like it were right: lower is better, and zero would be exact. Here it is on JevBench's published items, on its standard and hard tiers.
Measured by us on one RTX PRO 6000, vLLM 0.30.0, 2026-10-04, with JevBench's own measure, over ten equal-width bins of the probability; the evaluation card, section 3, has every calibration table and what was fitted on what.
Public boards
The JevBench board
JevBench is an outside board that sends decision questions to each system and scores its answers on intelligence (right answers, on open questions and on sealed ones it never published), calibration, speed and cost, and on a composite of them. Systems are in alphabetical order, and the live board has today's standings.
- On JevBench v1.6.1 (the board's file, October 2026), Decisio 31B scored 71.69 on the composite (95% interval 69.86 to 72.81) and Jev 1.13.0 scored 71.49 (69.14 to 72.40); the two intervals overlap.
- Decisio's 95% interval on the composite overlaps those of H2O-Lightning-4B, Quyet-1.0-Large and Jev 1.13.0, so these scores cannot be separated.
The composite, with its 95% interval
| System | Score | 95% interval |
|---|---|---|
| Cygnet | 68.55 | 64.42 to 69.94 |
| decider-12b v1 | 70.42 | 68.09 to 71.63 |
| decider-12b v2 | 70.88 | 68.54 to 72.21 |
| Decisio, Gemma 4 12B (ours) | 68.17 | 57.37 to 69.65 |
| Decisio, Gemma 4 31B (ours) | 71.69 | 69.86 to 72.81 |
| deck-31B | 68.68 | 67.07 to 69.74 |
| H2O-Lightning-4B v1.1 | 72.52 | 69.79 to 73.79 |
| Quyet-1.0-Large | 71.39 | 69.84 to 72.21 |
| torchcast-decision-12b | 69.91 | 67.22 to 71.47 |
| Winnow-12B Q8 | 68.89 | 66.45 to 70.46 |
| Jev 1.13.0 | 71.49 | 69.14 to 72.40 |
5cd8c1332226.The 12B rows' intervals are wide on the low side. Our temperatures were not fitted on JevBench, but we have read its published items (the evaluation card, section 7.4).
Decisio's rows as the board ran them: Decisio, Gemma 4 12B, run of 2026-10-06 on decisio v0.8.0; Decisio, Gemma 4 12B, run of 2026-10-07 on decisio v0.9.0; Decisio, Gemma 4 31B on decisio v0.8.0.
Axis by axis
- On JevBench v1.6.1, the 31B's sealed-set intelligence was 73.3 and Jev 1.13.0's 61.6; the open-set intelligence was 67.6 and 65.6.
- The sealed set was never published.
- On JevBench v1.6.1, Decisio 31B's axes were intelligence 70.4 (Jev 1.13.0 63.6), calibration 88.7 (90.6), speed 91.2 (91.5) and cost 51.7 (54.7).
- Decisio, Gemma 4 12B, run of 2026-10-0651.6 sealed53.1 open
- Decisio, Gemma 4 12B, run of 2026-10-0751.5 sealed53.1 open
- Decisio, Gemma 4 31B73.3 sealed67.6 open
- deck-31B75.8 sealed70.2 open
- H2O-Lightning-4B59.0 sealed61.1 open
- Quyet-1.0-Large71.6 sealed75.2 open
- Jev 1.13.061.6 sealed65.6 open
Every number, and what each axis measures
- Overall: composite score
- Intelligence: right answers
- Sealed questions: never published
- Calibration: probabilities you can trust
- Speed: faster answers
- Cost: higher is cheaper
| System | Overall | Intelligence | Sealed questions | Calibration | Speed | Cost |
|---|---|---|---|---|---|---|
| Cygnet | 68.55 | 54.8 | 51.3 | 87.0 | 91.8 | 56.4 |
| decider-12b v1 | 70.42 | 60.6 | 59.5 | 83.8 | 90.5 | 57.8 |
| decider-12b v2 | 70.88 | 63.0 | 63.6 | 82.0 | 90.5 | 57.8 |
| Decisio 12B (ours) | 68.17 | 52.3 | 51.6 | 89.2 | 87.0 | 59.3 |
| Decisio 31B (ours) | 71.69 | 70.4 | 73.3 | 88.7 | 91.2 | 51.7 |
| deck-31B | 68.68 | 73.0 | 75.8 | 82.2 | 86.7 | 49.7 |
| H2O-Lightning-4B | 72.52 | 60.0 | 59.0 | 90.0 | 92.6 | 60.3 |
| Quyet-1.0-Large | 71.39 | 73.4 | 71.6 | 90.0 | 86.9 | 50.5 |
| torchcast-decision-12b | 69.91 | 60.5 | 61.1 | 82.9 | 91.7 | 56.4 |
| Winnow-12B Q8 | 68.89 | 59.5 | 59.2 | 83.0 | 86.7 | 56.6 |
| Jev 1.13.0 (reference) | 71.49 | 63.6 | 61.6 | 90.6 | 91.5 | 54.7 |
The axes have no published intervals; the composite's is in the chart above.
Source: the board's file for revision v1.6.1; its rows for Decisio ran decisio v0.8.0.
Public boards
The Decision Index board
The Decision Index runs 38 public benchmarks in five areas and scores each system from 0 to 100. Its board lists decisio's rows from our submissions, in its data file of 2026-10-14.
decisio's rows on the board
| Row | Public index | Edition 0.3 index |
|---|---|---|
| Decisio, Gemma 4 31B | 58.09 | 58.55 |
| Decisio, Gemma 4 12B | 49.72 | 47.47 |
| Decisio, Qwen3.6-35B-A3B | 48.43 | 47.72 |
The rows as the board lists them: Gemma 4 31B on decisio 0.6.0; Gemma 4 12B on decisio 0.4.0; Qwen3.6-35B-A3B on decisio 0.4.0.
The evaluation card, section 8, has our own runs of the whole suite.
Beside other systems
Beside a hosted service and open entries
decisio's three bases beside TypeSafe's Jev 1.13 and three open-weights entries from the Decision Index's public board, as of 2026-10-05. Jev's and the other entries' values come only from the public boards and TypeSafe's public documentation; decisio's are our own runs on the Decision Index 0.2.1.
What you get
| Question | decisio | Jev 1.13 | Sources |
|---|---|---|---|
| Where does my data go? | Stays on the machine that runs it | TypeSafe's hosted API; not used for training | Sources |
| What does it cost? | No per-call price; you pay for the card | $42 per billion input tokens; output free | Sources |
| Does it run on my own GPU, Mac or laptop? | Yes: GPU, Mac with MLX, or a laptop with Ollama | No: Hosted API only; its documentation describes no self-hosted option | Sources |
| Longest document? | At least 32,768 tokens on a Gemma base, and up to 98,304 on the 31B, as the card holds | 32k tokens for the state plus the longest question (64k per request) | Sources |
| Options per question? | Up to 255 | Up to 255 on a choice | Sources |
| Many questions in one read? | Yes: The state is read once and shared by every question | Yes: Every question in a request is evaluated in parallel | Sources |
| Images? | Yes: Photos in the state; measured on the Qwen base only | No: Text only | Sources |
| Probabilities I can trust? | Yes: Fitted per base; each base's calibration error is under Confidence, above | Yes: Trained for calibrated decisions, in its documentation | Sources |
| Can I teach it with my own examples? | Yes: POST /v1/tasks fits calibration and an intent head to your labelled examples, and certifies which answers to trust at the error rate you pick; the model stays frozen | No: Not fine-tuned on customer data; shaped through the request | Sources |
| Same answer every time? | Qwen: bit for bit. The Gemma bases: the same top answer on one running server, with the exact numbers able to move | Not stated in its documentation; an alias moves when a release ships | Sources |
| Licence? | Apache-2.0 | A hosted service under TypeSafe's customer agreements | Sources |
Sources, row by row 11 rows
Each statement about Jev is what TypeSafe's public documentation states, quoted in snapshots/typesafe_docs.json with each page's hash, read 2026-10-05 at 21:44 UTC.
Where a row says the documentation does not state something, that is about the pages read, not a claim about the service.
- Where does my data go?
- What does it cost?
- decisio (Price)
- no per-call price; the card's cost (section 1, e)
- Jev 1.13 (Price)
- "$42 / $0.042" per billion / million tokens, "Charged per input token. Output tokens are free." (models)
- Does it run on my own GPU, Mac or laptop?
- decisio (Self-hosting)
- yes: one 80 or 96 GB card on vLLM, the Docker image, or a Mac (below)
- Jev 1.13 (Self-hosting)
- served by "the same endpoint,
POST /v1/systemone"; the pages read describe the hosted API and no self-hosted option (models)
- decisio (Mac and Ollama)
- Qwen, Gemma 4 12B and Gemma 4 31B (up to 16,383 tokens of state) on Apple silicon with MLX; the Qwen base on Ollama (
aminroudaki/decisio), with Ollama's own prompt and no calibration - Jev 1.13 (Mac and Ollama)
- the pages read describe the hosted API only
- Longest document?
- decisio (Context)
- 32,768 tokens per prompt: the state plus one question
- Jev 1.13 (Context)
- "64k tokens per request; 32k tokens for
stateplus the longest question" (models)
- Options per question?
- decisio (Options per question)
- up to 255 named options per choice (more is 422, as there); a score has no cap on its levels
- Jev 1.13 (Options per question)
- "a maximum of 255 options per Choice"; a Score "accepts up to 10" levels (API)
- Many questions in one read?
- decisio (Several questions per request)
- the state is read once and shared by every question in the request
- Jev 1.13 (Several questions per request)
- "System One models evaluate every question in a request in parallel." (primitives)
- Images?
- decisio (Image input)
- photos in the state, through a second engine on the same card (
--image-model); measured on the Qwen base only - Jev 1.13 (Image input)
- "Text only. String, JSON object, or array of text values. No image, audio, or video input." (models)
- Probabilities I can trust?
- decisio (Calibration)
- fitted temperatures per base; JevBench ECE on the standard and hard tiers: Qwen 0.121 and 0.043, Gemma 4 12B 0.033 and 0.085, Gemma 4 31B 0.035 and 0.091
- Jev 1.13 (Calibration)
- "System One models are trained for calibrated decisions: their probabilities are optimized against outcomes to reflect uncertainty." (System One)
- Can I teach it with my own examples?
- decisio (Teaching from labelled examples)
POST /v1/tasksfits a per-task calibration and, for long option lists, an intent head on your labelled examples; the model stays frozen- Jev 1.13 (Teaching from labelled examples)
- "Jev is not fine-tuned or LoRA-adapted with customer data", and "You shape its answers to your domain through the request rather than through per-account weights" (models)
- Same answer every time?
- decisio (Repeatability)
- checkpoints at pinned revisions; Qwen: a repeated request returns the same probabilities bit for bit; Gemma 4 12B: probabilities move between two freshly started servers (up to 0.060 on 200 requests, one exact tie changed) and between a first read and a cached one (up to 0.113), so a repeat is not bit for bit; Gemma 4 31B: a request repeats exactly on a freshly started server; on a server that has already answered it, a repeat can differ (5 of 200 items, up to 0.031, no top answer changed, 31B on vLLM 0.30.0 and 0.31.0); across sessions near-tied answers can move (Evaluation card sections 5 to 7)
- Jev 1.13 (Repeatability)
- "An alias moves when a new release ships, so the answers behind it can change without a change on your side." The pages read do not state whether a repeated request returns the same probabilities (models)
- Licence?
- decisio (Licence)
- Apache-2.0; the weights are Qwen's under Apache-2.0 and Google's Gemma 4 under Apache-2.0
- Jev 1.13 (Licence)
- a hosted service under TypeSafe's customer agreements, which "govern your use of TypeSafe" (legal)
The headline
| Measure | DecisioQwen3.6-35B-A3B | DecisioGemma 4 12B | DecisioGemma 4 31B | Jev 1.13 | Surogate Rune26B-A4B v3 |
|---|---|---|---|---|---|
| Decision Index 0.2.1 (0 to 100) | 48.06 | 49.43 | 57.58 | 57.91 | 57.44 |
| Knowledge & Reasoning | 32.45 | 31.37 | 45.57 | 51.40 | 43.36 |
| Language Understanding | 51.39 | 51.66 | 61.02 | 62.02 | 63.06 |
| Retrieval & Classification | 53.56 | 58.00 | 62.75 | 55.42 | 63.52 |
| Tools & Automation | 68.43 | 71.62 | 75.04 | 75.09 | 71.22 |
| Arts & Human Taste | 31.57 | 32.59 | 37.43 | 37.66 | 41.90 |
| On JevBench's 231 published questions, correct | 200 | 200 | 213 | 200 | not compared (h) |
| JevBench hard tier, correct | 82 of 111 | 82 of 111 | 93 of 111 | not compared (a) | not compared (h) |
| System | Latency, median per request | Price or self-hosting cost, one pass over the 38 index benchmarks | Context length | What it is |
|---|---|---|---|---|
| DecisioQwen3.6-35B-A3B | 70.5 ms (b) | $6.98 (e) | 32,768 tokens per prompt | official Qwen weights, frozen, letters readout |
| DecisioGemma 4 12B | 37.8 ms (b) | $6.92 (e) | the largest the card holds, 32,768 to 65,536 tokens per prompt | official Gemma weights, frozen, letters readout |
| DecisioGemma 4 31B | 56.0 ms (b) | $10.28 (e) | the largest the card holds, 32,768 to 98,304 tokens per prompt | official Gemma weights, frozen, FP8 on load, letters readout |
| Jev 1.13 | 524.1 ms (c) | $6.05 (f) | 64k tokens per request; 32k tokens for the state plus the longest question (g) | hosted model, TypeSafe's API |
| Surogate Rune26B-A4B v3 | 120.5 ms (d) | $16.53 (e) | not on the board | full fine-tune of google/gemma-4-26B-A4B-it |
| Decider chatGemma-4-31B | 108.5 ms (d) | $22.18 (e) | not on the board | an inference technique on google/gemma-4-31B-it |
| pplx-decider-v1-27b | 101.4 ms (d) | $24.94 (e) | not on the board | full fine-tune of Qwen/Qwen3.8-27B |
The lettered notes 8 notes
(a) JevBench's board reports Jev's hard tier over 220 questions, 109 of them held out and never published, so it is not the same item set as the 111 published ones we can run.
(b) Our server time on one RTX PRO 6000 Blackwell: the Decision Index kit's HTTP wall time to a server on the same machine, one request at a time, over all 150,759 requests.
(c) The board's own measurement of TypeSafe's hosted API: an HTTPS round trip over the internet from its lab, one request at a time, on its latency sample. It includes the network, so it is not the same measurement as (b) and (d).
(d) The board's on-card median on one RTX PRO 6000, one request at a time, on its latency sample.
(e) Self-hosted, estimated as mean request latency × 150,759 requests at $1.48 per card-hour, what a rented card for our runs cost; for the other entries, with the board's mean latency. One request at a time throughout; a server answering requests concurrently would cost less per pass.
(f) The board's recorded API cost of Jev's run over the same benchmarks, at TypeSafe's tariff of $0.042 per million input tokens, output tokens free.
(g) From TypeSafe's documentation (section 3).
(h) Not on JevBench's board.
Every index benchmark
Every benchmark, by area 38 rows
One row per benchmark, grouped by area, with the coverage-adjusted value that feeds the index (raw on the board); ForecastBench shows its Brier loss, where lower is better.
n is the number of items behind the interval: the smallest of the benchmark's cases, our scored requests and Jev's cases.
Each interval is in runs/2026-10-05_comparison/results.json, and tables.md there is these tables as the script writes them.
These are the values the index counts, so a few differ from the base table above: within 0.001 on the 12B, except GPQA Diamond (two of 196 items).
Knowledge & Reasoning
| Benchmark | n | Qwen3.6-35B-A3B | Gemma 4 12B | Gemma 4 31B | Jev 1.13 | Rune26B-A4B v3 | Decider chatGemma-4-31B | pplx-decider-v1-27b |
|---|---|---|---|---|---|---|---|---|
| GPQA Diamond, accuracy | 196 | 0.510 | 0.388 | 0.520 | 0.786 | 0.469 | 0.490 | 0.495 |
| GSM8K, accuracy | 1,319 | 0.544 | 0.599 | 0.805 | 0.799 | 0.797 | 0.826 | 0.674 |
| ChessBench, accuracy | 5,000 | 0.162 | 0.165 | 0.220 | 0.172 | 0.187 | 0.223 | 0.172 |
| MuSR, accuracy | 752 | 0.581 | 0.581 | 0.640 | 0.661 | 0.649 | 0.642 | 0.618 |
| SATA-Bench, case exact accuracy | 1,650 | 0.232 | 0.264 | 0.323 | 0.264 | 0.348 | 0.293 | 0.299 |
| CRUXEval, accuracy | 570 | 0.625 | 0.654 | 0.832 | 0.730 | 0.744 | 0.793 | 0.749 |
| CLadder, accuracy | 5,000 | 0.622 | 0.634 | 0.764 | 0.726 | 0.727 | 0.746 | 0.745 |
| HLE, accuracy | 501 | 0.114 | 0.106 | 0.150 | 0.204 | 0.106 | 0.148 | 0.120 |
| MMLU-Pro, accuracy | 12,032 | 0.613 | 0.550 | 0.694 | 0.827 | 0.672 | 0.696 | 0.645 |
| BBH, accuracy | 5,507 | 0.694 | 0.691 | 0.762 | 0.929 | 0.811 | 0.762 | 0.781 |
Language Understanding
| Benchmark | n | Qwen3.6-35B-A3B | Gemma 4 12B | Gemma 4 31B | Jev 1.13 | Rune26B-A4B v3 | Decider chatGemma-4-31B | pplx-decider-v1-27b |
|---|---|---|---|---|---|---|---|---|
| ContractNLI, macro-F1 | 123 | 0.733 | 0.743 | 0.726 | 0.717 | 0.770 | 0.736 | 0.781 |
| ANLI, macro-F1 | 3,200 | 0.686 | 0.702 | 0.737 | 0.748 | 0.735 | 0.732 | 0.707 |
| WinoGrande, accuracy | 1,267 | 0.808 | 0.730 | 0.852 | 0.919 | 0.860 | 0.837 | 0.852 |
| HellaSwag, accuracy | 10,042 | 0.940 | 0.867 | 0.923 | 0.945 | 0.924 | 0.920 | 0.940 |
| ACOS, per-review F1 | 400 | 0.174 | 0.155 | 0.215 | 0.295 | 0.268 | 0.188 | 0.204 |
| FinEntity, macro-F1 | 979 | 0.803 | 0.905 | 0.931 | 0.870 | 0.884 | 0.909 | 0.929 |
| iSarcasmEval, Sarcasm F1 · track A, English | 1,400 | 0.474 | 0.427 | 0.506 | 0.505 | 0.604 | 0.511 | 0.603 |
| VAST, macro-F1 | 3,006 | 0.490 | 0.591 | 0.687 | 0.646 | 0.766 | 0.732 | 0.708 |
| NLI4CT, macro-F1 | 5,500 | 0.772 | 0.813 | 0.835 | 0.841 | 0.804 | 0.829 | 0.848 |
| RAGTruth, F1 on hallucinated class | 2,700 | 0.702 | 0.696 | 0.783 | 0.765 | 0.768 | 0.769 | 0.803 |
Retrieval & Classification
| Benchmark | n | Qwen3.6-35B-A3B | Gemma 4 12B | Gemma 4 31B | Jev 1.13 | Rune26B-A4B v3 | Decider chatGemma-4-31B | pplx-decider-v1-27b |
|---|---|---|---|---|---|---|---|---|
| BANKING77, macro-F1 | 3,080 | 0.746 | 0.729 | 0.784 | 0.797 | 0.838 | 0.791 | 0.790 |
| CLINC150+OOS, macro-F1 | 5,500 | 0.822 | 0.872 | 0.901 | 0.893 | 0.874 | 0.912 | 0.878 |
| BRIGHT, nDCG@10 | 220 | 0.444 | 0.471 | 0.439 | 0.475 | 0.463 | 0.436 | 0.487 |
| Amazon ESCI, macro-F1 | 5,000 | 0.450 | 0.535 | 0.540 | 0.552 | 0.553 | 0.531 | 0.551 |
| PhishNChips phishing decisions, accuracy | 2,000 | 0.752 | 0.813 | 0.875 | 0.625 | 0.809 | 0.875 | 0.600 |
| HoVer, accuracy | 4,000 | 0.700 | 0.693 | 0.756 | 0.729 | 0.807 | 0.764 | 0.742 |
Tools & Automation
| Benchmark | n | Qwen3.6-35B-A3B | Gemma 4 12B | Gemma 4 31B | Jev 1.13 | Rune26B-A4B v3 | Decider chatGemma-4-31B | pplx-decider-v1-27b |
|---|---|---|---|---|---|---|---|---|
| BFCL, case exact accuracy | 1,694 | 0.960 | 0.962 | 0.979 | 0.958 | 0.948 | 0.980 | 0.976 |
| ToolRet, nDCG@10 | 685 | 0.625 | 0.622 | 0.613 | 0.653 | 0.644 | 0.636 | 0.674 |
| API-Bank, accuracy | 508 | 0.817 | 0.870 | 0.854 | 0.882 | 0.833 | 0.850 | 0.841 |
| Home appliance simulator, case exact accuracy | 88 | 0.398 | 0.443 | 0.614 | 0.523 | 0.466 | 0.625 | 0.739 |
| When2Call, accuracy | 3,652 | 0.714 | 0.761 | 0.772 | 0.810 | 0.760 | 0.769 | 0.817 |
Arts & Human Taste
| Benchmark | n | Qwen3.6-35B-A3B | Gemma 4 12B | Gemma 4 31B | Jev 1.13 | Rune26B-A4B v3 | Decider chatGemma-4-31B | pplx-decider-v1-27b |
|---|---|---|---|---|---|---|---|---|
| BPoMP, accuracy | 811 | 0.904 | 0.910 | 0.894 | 0.909 | 0.900 | 0.906 | 0.939 |
| Humicroedit, accuracy | 2,628 | 0.608 | 0.617 | 0.625 | 0.619 | 0.622 | 0.638 | 0.624 |
| POP909-CL, accuracy | 2,000 | 0.142 | 0.060 | 0.250 | 0.166 | 0.661 | 0.279 | 0.378 |
| cfcolor, accuracy | 5,000 | 0.600 | 0.624 | 0.639 | 0.644 | 0.626 | 0.626 | 0.644 |
| ForecastBench, Brier loss (lower is better) | 10,139 | 0.228 | 0.202 | 0.207 | 0.174 | 0.203 | 0.202 | 0.195 |
| Habermas Machine, accuracy | 1,676 | 0.447 | 0.465 | 0.484 | 0.459 | 0.422 | 0.479 | 0.418 |
| New Yorker, accuracy | 528 | 0.688 | 0.633 | 0.739 | 0.701 | 0.741 | 0.739 | 0.703 |
Each value and interval is in runs/2026-10-05_comparison/: runs/2026-10-05_comparison/; Jev's values are the board's, as the evaluation card, section 8.1, reads them. No figure here comes from a call of ours to TypeSafe's API.
The recorded demos, every player
The Demos page shows decisio's own runs; here are the other players beside them.
The players 8 rows
| row | model ID | date | route | serving provider |
|---|---|---|---|---|
| Decisio, Qwen3.6-35B-A3B base | Qwen/Qwen3.6-35B-A3B-FP8 @95a723d0 served by decisio v0.6.0 | 2026-10-05 | local server on the card | |
| Decisio, Gemma 4 12B base | google/gemma-4-12B-it @707f0a3b served by decisio v0.6.0 | 2026-10-05 | local server on the card | |
| Decisio, Gemma 4 31B base | google/gemma-4-31B-it @842da379, FP8 on load, served by decisio v0.6.0 | 2026-10-05 | local server on the card | |
| Cygnet | google/gemma-4-12B-it @707f0a3b with the cygnet-recipe decision server @3cf591c6 (T 3.4) | 2026-10-03 | local server on the card | |
| Jev 1.13 through its public API | jev-1.13.0 | 2026-10-03 | TypeSafe public API | TypeSafe |
| google/gemini-3.8-flash | google/gemini-3.8-flash | 2026-10-03 | OpenRouter | Google AI Studio |
| anthropic/claude-haiku-4.5 | anthropic/claude-haiku-4.5 | 2026-10-03 | OpenRouter | Anthropic |
| openai/gpt-6-luna | openai/gpt-6-luna | 2026-10-03 | OpenRouter | OpenAI |
Browser agent (10 runs of each task) 8 rows
| player | travel completed | travel decisions right | reading room completed | reading room decisions right | latency p50 / p95 |
|---|---|---|---|---|---|
| Decisio, Qwen3.6-35B-A3B base | 10/10 | 50/70 | 10/10 | 80/140 | 141 / 174 |
| Decisio, Gemma 4 12B base | 10/10 | 60/60 | 10/10 | 20/20 | 141 / 275 |
| Decisio, Gemma 4 31B base | 10/10 | 40/50 | 10/10 | 20/20 | 184 / 417 |
| Cygnet | 10/10 | 60/60 | 10/10 | 20/20 | 58 / 253 |
| Jev 1.13 through its public API | 10/10 | 60/60 | 10/10 | 20/20 | 130 / 185 |
| google/gemini-3.8-flash | 10/10 | 60/60 | 10/10 | 20/20 | 1308 / 2030 |
| anthropic/claude-haiku-4.5 | 10/10 | 40/50 | 10/10 | 20/20 | 1248 / 1767 |
| openai/gpt-6-luna | 10/10 | 60/68 | 10/10 | 20/20 | 2878 / 4464 |
Driving 8 rows
| player | lockstep: drives passed | lockstep: motion errors / motion answers | realtime: drives passed | realtime: motion errors / latency effects | decisions per second (lockstep, realtime) | latency p50 / p95 (lockstep) |
|---|---|---|---|---|---|---|
| Decisio, Qwen3.6-35B-A3B base | 3 of 3 | 8 / 545 | 3 of 3 | 5 / 2 | 7.74, 3.12 | 102 / 158 |
| Decisio, Gemma 4 12B base | 3 of 3 | 25 / 792 | 3 of 3 | 6 / 4 | 4.01, 2.99 | 218 / 343 |
| Decisio, Gemma 4 31B base | 3 of 3 | 5 / 568 | 3 of 3 | 0 / 3 | 2.70, 2.37 | 341 / 569 |
| Cygnet | 3 of 3 | 0 / 574 | 3 of 3 | 0 / 7 | 2.49, 2.30 | 371 / 693 |
| Jev 1.13 through its public API | 3 of 3 | 0 / 711 | 3 of 3 | 0 / 2 | 6.58, 3.03 | 126 / 178 |
| google/gemini-3.8-flash | 3 of 3 | 0 / 564 | 1 of 3 | 1 / 98 | 0.59, 0.40 | 1319 / 3853 |
| anthropic/claude-haiku-4.5 | 3 of 3 | 0 / 609 | 3 of 3 | 0 / 12 | 0.89, 0.96 | 1026 / 1574 |
| openai/gpt-6-luna | 3 of 3 | 0 / 848 | 1 of 3 | 0 / 109 | 0.30, 0.08 | 3195 / 5911 |
Pong (5 games of up to 45 s, seeds 20260917 to 20260921) 8 rows
| player | agrees with the oracle while the ball approaches | decisions on approach | decisions per second | latency p50 / p95 | returns per game |
|---|---|---|---|---|---|
| Decisio, Qwen3.6-35B-A3B base | 60% [53, 65] | 531 | 22.9 | 44 / 47 | 22.8 [12.4, 32.8] |
| Decisio, Gemma 4 12B base | 62% [56, 66] | 539 | 22.8 | 48 / 50 | 23.2 [21.2, 24.8] |
| Decisio, Gemma 4 31B base | 85% [82, 88] | 1679 | 15.0 | 68 / 69 | 84.2 [83.0, 86.6] |
| Cygnet | 47% [41, 53] | 459 | 22.9 | 41 / 69 | 19.2 [12.8, 26.4] |
| Jev 1.13 through its public API | 96% [94, 98] | 913 | 8.2 | 116 / 166 | 45.8 [45.4, 46.0] |
| google/gemini-3.8-flash | 98% [94, 100] | 95 | 0.87 | 1131 / 1570 | 5.0 |
| anthropic/claude-haiku-4.5 | 69% [55, 86] | 139 | 1.29 | 745 / 1000 | 6.8 [6.4, 7.0] |
| openai/gpt-6-luna | 98% [95, 100] | 58 | 0.62 | 1460 / 2724 | 3.4 [3.0, 3.8] |
What next
Before you rely on a number
- Each figure is one card, one run: your card, host and load will move the times.
- Every time on this page is server time, one request at a time; Scale covers a busy server.
- Several figures were measured on earlier releases of the same models; each says which.
- Every decisio figure here was measured on the plain layout, the text then the question; the Gemma models now serve the header layout by default, which answered more accurately on most of what was measured (Choose the prompt layout).